

Buy Latest Dec 17, 2025 Databricks-Certified-Data-Analyst-Associate Exam Q&A PDF - One Year Free Update
Download the Latest Databricks-Certified-Data-Analyst-Associate Dump - 2025 Databricks-Certified-Data-Analyst-Associate Exam Questions
Databricks Databricks-Certified-Data-Analyst-Associate Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 13
What is a benefit of using Databricks SQL for business intelligence (Bl) analytics projects instead of using third-party Bl tools?
- A. Automated alerting systems
- B. Advanced dashboarding capabilities
- C. Simultaneous multi-user support
- D. Computations, data, and analytical tools on the same platform
Answer: D
Explanation:
Databricks SQL offers a unified platform where computations, data storage, and analytical tools coexist seamlessly. This integration allows business intelligence (BI) analytics projects to be executed more efficiently, as users can perform data processing and analysis without the need to transfer data between disparate systems. By consolidating these components, Databricks SQL streamlines workflows, reduces latency, and enhances data governance. While third-party BI tools may offer advanced dashboarding capabilities, simultaneous multi-user support, and automated alerting systems, they often require integration with separate data processing platforms, which can introduce complexity and potential inefficiencies.
NEW QUESTION # 14
Which statement describes descriptive statistics?
- A. A branch of statistics that uses summary statistics to categorically describe and summarize data.
- B. A branch of statistics that uses a variety of data analysis techniques to infer properties of an underlying distribution of probability.
- C. A branch of statistics that uses quantitative variables that must take on a finite or countably infinite set of values.
- D. A branch of statistics that uses summary statistics to quantitatively describe and summarize data.
Answer: D
NEW QUESTION # 15
A data analyst has created a Query in Databricks SQL, and now they want to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which of the following steps will they need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. They will need to decide on a single data visualization to add to the dashboard.
- B. They will need to copy the Query and create one data visualization per query.
- C. They will need to add two separate visualizations to the dashboard based on the same Query.
- D. They will need to create two separate dashboards.
- E. They will need to alter the Query to return two separate sets of results.
Answer: C
Explanation:
A data analyst can create multiple visualizations from the same query in Databricks SQL by clicking the + button next to the Results tab and selecting Visualization. Each visualization can have a different type, name, and configuration. To add a visualization to a dashboard, the data analyst can click the vertical ellipsis button beneath the visualization, select + Add to Dashboard, and choose an existing or new dashboard. The data analyst can repeat this process for each visualization they want to add to the same dashboard. Reference: Visualization in Databricks SQL, Visualize queries and create a dashboard in Databricks SQL
NEW QUESTION # 16
A data analyst has created a Query in Databricks SQL, and now they want to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which of the following steps will they need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. They will need to decide on a single data visualization to add to the dashboard.
- B. They will need to copy the Query and create one data visualization per query.
- C. They will need to add two separate visualizations to the dashboard based on the same Query.
- D. They will need to create two separate dashboards.
- E. They will need to alter the Query to return two separate sets of results.
Answer: C
Explanation:
A data analyst can create multiple visualizations from the same query in Databricks SQL by clicking the + button next to the Results tab and selecting Visualization. Each visualization can have a different type, name, and configuration. To add a visualization to a dashboard, the data analyst can click the vertical ellipsis button beneath the visualization, select + Add to Dashboard, and choose an existing or new dashboard. The data analyst can repeat this process for each visualization they want to add to the same dashboard. Reference: Visualization in Databricks SQL, Visualize queries and create a dashboard in Databricks SQL
NEW QUESTION # 17
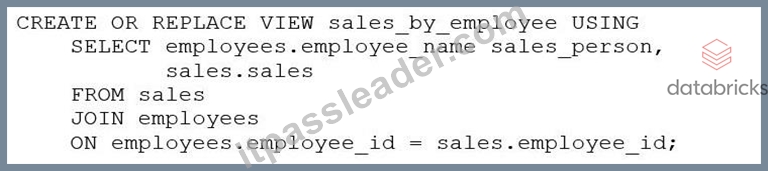
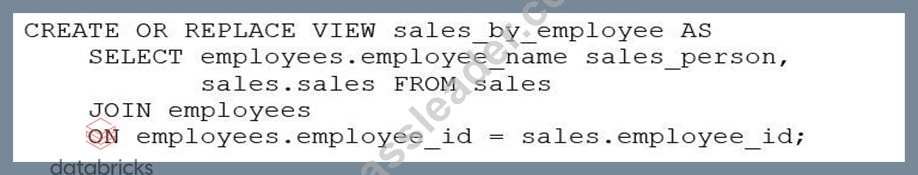
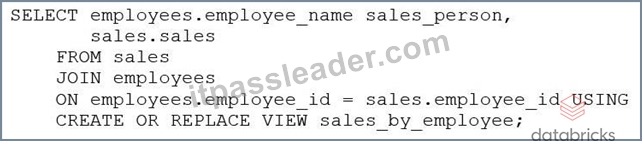
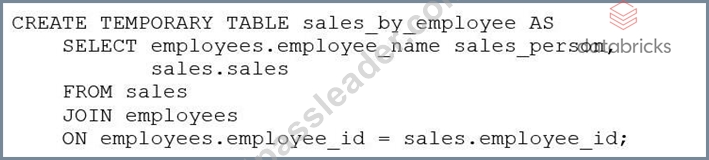
A business analyst has been asked to create a data entity/object called sales_by_employee. It should always stay up-to-date when new data are added to the sales table. The new entity should have the columns sales_person, which will be the name of the employee from the employees table, and sales, which will be all sales for that particular sales person. Both the sales table and the employees table have an employee_id column that is used to identify the sales person.
Which of the following code blocks will accomplish this task?
- A.
- B.
- C.
- D.
Answer: B
Explanation:
The SQL code provided in Option D is the correct way to create a view named sales_by_employee that will always stay up-to-date with the sales and employees tables. The code uses the CREATE OR REPLACE VIEW statement to define a new view that joins the sales and employees tables on the employee_id column. It selects the employee_name as sales_person and all sales for each employee, ensuring that the data entity/object is always up-to-date when new data are added to these tables.
NEW QUESTION # 18
A data analyst has a managed table table_name in database database_name. They would now like to remove the table from the database and all of the data files associated with the table. The rest of the tables in the database must continue to exist.
Which of the following commands can the analyst use to complete the task without producing an error?
- A. DROP TABLE database_name.table_name;
- B. DELETE TABLE table_name FROM database_name;
- C. DROP DATABASE database_name;
- D. DELETE TABLE database_name.table_name;
- E. DROP TABLE table_name FROM database_name;
Answer: A
NEW QUESTION # 19
A data engineering team has created a Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables. The microbatches are triggered every minute.
A data analyst has created a dashboard based on this gold-level dat
a. The project stakeholders want to see the results in the dashboard updated within one minute or less of new data becoming available within the gold-level tables.
Which of the following cautions should the data analyst share prior to setting up the dashboard to complete this task?
- A. The streaming cluster is not fault tolerant
- B. The dashboard cannot be refreshed that quickly
- C. The streaming data is not an appropriate data source for a dashboard
- D. The gold-level tables are not appropriately clean for business reporting
- E. The required compute resources could be costly
Answer: E
Explanation:
A Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables every minute requires a high level of compute resources to handle the frequent data ingestion, processing, and writing. This could result in a significant cost for the organization, especially if the data volume and velocity are large. Therefore, the data analyst should share this caution with the project stakeholders before setting up the dashboard and evaluate the trade-offs between the desired refresh rate and the available budget. The other options are not valid cautions because:
B . The gold-level tables are assumed to be appropriately clean for business reporting, as they are the final output of the data engineering pipeline. If the data quality is not satisfactory, the issue should be addressed at the source or silver level, not at the gold level.
C . The streaming data is an appropriate data source for a dashboard, as it can provide near real-time insights and analytics for the business users. Structured Streaming supports various sources and sinks for streaming data, including Delta Lake, which can enable both batch and streaming queries on the same data.
D . The streaming cluster is fault tolerant, as Structured Streaming provides end-to-end exactly-once fault-tolerance guarantees through checkpointing and write-ahead logs. If a query fails, it can be restarted from the last checkpoint and resume processing.
E . The dashboard can be refreshed within one minute or less of new data becoming available in the gold-level tables, as Structured Streaming can trigger micro-batches as fast as possible (every few seconds) and update the results incrementally. However, this may not be necessary or optimal for the business use case, as it could cause frequent changes in the dashboard and consume more resources. Reference: Streaming on Databricks, Monitoring Structured Streaming queries on Databricks, A look at the new Structured Streaming UI in Apache Spark 3.0, Run your first Structured Streaming workload
NEW QUESTION # 20
What is used as a compute resource for Databricks SQL?
- A. Single-node clusters
- B. Downstream BI tools integrated with Databricks SQL
- C. SQL warehouses
- D. Standard clusters
Answer: C
NEW QUESTION # 21
A data analyst has been asked to configure an alert for a query that returns the income in the accounts_receivable table for a date range. The date range is configurable using a Date query parameter.
The Alert does not work.
Which of the following describes why the Alert does not work?
- A. Alerts don't work with queries that access tables.
- B. Queries that return results based on dates cannot be used with Alerts.
- C. Queries that use query parameters cannot be used with Alerts.
- D. The wrong query parameter is being used. Alerts only work with drogdown list query parameters, not dates.
- E. The wrong query parameter is being used. Alerts only work with Date and Time query parameters.
Answer: C
Explanation:
The reason the alert is not functioning as expected is because Databricks SQL Alerts do not support query parameters. This limitation applies to all types of parameters, including date parameters.
Here's why:
Alerts require static, deterministic query results so they can compare values consistently during scheduled executions.
When a query includes parameters (e.g., a date range parameter), its results may change based on user input or the default value set in the query editor.
However, Databricks SQL Alerts will always use the default value set for the parameter at the time the alert is created. This means the alert doesn't dynamically adapt to new date ranges and will not reflect changes unless the query is manually updated.
As a result, if the business logic behind the alert depends on changing date ranges or any user input, the alert will not trigger correctly, or may never trigger at all.
Therefore, the correct explanation contradicts Option B, which is incorrect in saying that alerts cannot work with date-based queries at all. In fact, they can-as long as the query is static (i.e., without parameters).
Reference:
Databricks SQL Alerts Documentation
Databricks Knowledge: "You cannot use alerts with queries that contain parameters."
NEW QUESTION # 22
What describes the variance of a set of values?
- A. Variance is a measure of central tendency of a set of values.
- B. Variance is a measure of how far a single observed value is from a set ot va IN
- C. Variance is a measure of how far an observed value is from the variable's maximum or minimum value.
- D. Variance is a measure of how far a set of values is spread out from the sets central value.
Answer: D
Explanation:
Variance is a statistical measure that quantifies the dispersion or spread of a set of values around their mean (central value). It is calculated by taking the average of the squared differences between each value and the mean of the dataset. A higher variance indicates that the data points are more spread out from the mean, while a lower variance suggests that they are closer to the mean. This measure is fundamental in statistics to understand the degree of variability within a dataset.WikipediaWikipedia+1Investopedia+1
NEW QUESTION # 23
The stakeholders.customers table has 15 columns and 3,000 rows of dat
a. The following command is run: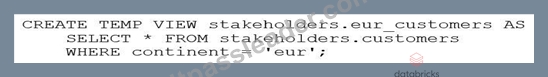
After running SELECT * FROM stakeholders.eur_customers, 15 rows are returned. After the command executes completely, the user logs out of Databricks.
After logging back in two days later, what is the status of the stakeholders.eur_customers view?
- A. The view remains available but attempting to SELECT from it results in an empty result set because data in views are automatically deleted after logging out.
- B. The view has been dropped.
- C. The view has been converted into a table.
- D. The view remains available and SELECT * FROM stakeholders.eur_customers will execute correctly.
- E. The view is not available in the metastore, but the underlying data can be accessed with SELECT * FROM delta. `stakeholders.eur_customers`.
Answer: D
Explanation:
In Databricks, a view is a saved SQL query definition that references existing tables or other views. Once created, a view remains persisted in the metastore (such as Unity Catalog or Hive Metastore) until it is explicitly dropped.
Key points:
Views do not store data themselves but reference data from underlying tables.
Logging out or being inactive does not delete or alter views.
Unless a user or admin explicitly drops the view or the underlying data/table is deleted, the view continues to function as expected.
Therefore, after logging back in-even days later-a user can still run SELECT * FROM stakeholders.eur_customers, and it will return the same data (provided the underlying table hasn't changed).
NEW QUESTION # 24
A data analyst has recently joined a new team that uses Databricks SQL, but the analyst has never used Databricks before. The analyst wants to know where in Databricks SQL they can write and execute SQL queries.
On which of the following pages can the analyst write and execute SQL queries?
- A. Dashboards page
- B. Alerts page
- C. Data page
- D. Queries page
- E. SQL Editor page
Answer: E
Explanation:
The SQL Editor page is where the analyst can write and execute SQL queries in Databricks SQL. The SQL Editor page has a query pane where the analyst can type or paste SQL statements, and a results pane where the analyst can view the query results in a table or a chart. The analyst can also browse data objects, edit multiple queries, execute a single query or multiple queries, terminate a query, save a query, download a query result, and more from the SQL Editor page. Reference: Create a query in SQL editor
NEW QUESTION # 25
Which of the following approaches can be used to connect Databricks to Fivetran for data ingestion?
- A. Use Delta Live Tables to establish a cluster for Fivetran to interact with
- B. Use Partner Connect's automated workflow to establish a SQL warehouse (formerly known as a SQL endpoint) for Fivetran to interact with
- C. Use Workflows to establish a cluster for Fivetran to interact with
- D. Use Workflows to establish a SQL warehouse (formerly known as a SQL endpoint) for Fivetran to interact with
- E. Use Partner Connect's automated workflow to establish a cluster for Fivetran to interact with
Answer: E
Explanation:
Partner Connect is a feature that allows you to easily connect your Databricks workspace to Fivetran and other ingestion partners using an automated workflow. You can select a SQL warehouse or a cluster as the destination for your data replication, and the connection details are sent to Fivetran. You can then choose from over 200 data sources that Fivetran supports and start ingesting data into Delta Lake. Reference: Connect to Fivetran using Partner Connect, Use Databricks with Fivetran
NEW QUESTION # 26
What describes Partner Connect in Databricks?
- A. It is a feature that runs Databricks partner tools on a Databricks SQL Warehouse (formerly known as a SQL endpoint).
- B. it allows for free use of Databricks partner tools through a common API.
- C. It exposes connection information to third-party tools via Databricks partners.
- D. it allows multi-directional connection between Databricks and Databricks partners easier.
Answer: D
Explanation:
Databricks Partner Connect is designed to simplify and streamline the integration between Databricks and its technology partners. It provides a unified interface within the Databricks platform that facilitates the discovery and connection to a variety of data, analytics, and AI tools. By automating the configuration of necessary resources such as clusters, tokens, and connection files, Partner Connect enables seamless, bi-directional data flow between Databricks and partner solutions. This integration enhances the overall functionality of the Databricks Lakehouse by allowing users to easily incorporate external tools and services into their workflows, thereby expanding the platform's capabilities and fostering a more cohesive data ecosystem.https://www.databricks.com/blog/2021/11/18/now-generally-available-introducing-databricks-partner-connect-to-discover-and-connect-popular-data-and-ai-tools-to-the-lakehouse?utm_source=chatgpt.com
NEW QUESTION # 27
A data analyst needs to share a Databricks SQL dashboard with stakeholders that are not permitted to have accounts in the Databricks deployment. The stakeholders need to be notified every time the dashboard is refreshed.
Which approach can the data analyst use to accomplish this task with minimal effort/
- A. By adding the stakeholders' email addresses to the refresh schedule subscribers list
- B. By downloading the dashboard as a PDF and emailing it to the stakeholders each time it is refreshed
- C. By granting the stakeholders' email addresses permissions to the dashboard
- D. By granting the stakeholders' email addresses to the SQL Warehouse (formerly known as endpoint) subscribers list
Answer: A
Explanation:
To share a Databricks SQL dashboard with stakeholders who do not have accounts in the Databricks deployment and ensure they are notified upon each refresh, the data analyst can add the stakeholders' email addresses to the dashboard's refresh schedule subscribers list. This approach allows the stakeholders to receive email notifications containing the latest dashboard updates without requiring them to have direct access to the Databricks workspace. This method is efficient and minimizes effort, as it automates the notification process and ensures stakeholders remain informed of the most recent data insights.
NEW QUESTION # 28
Which location can be used to determine the owner of a managed table?
- A. Review the Owner field in the database page using Data Explorer
- B. Review the Owner field in the table page using Catalog Explorer
- C. Review the Owner field in the schema page using Data Explorer
- D. Review the Owner field in the table page using the SQL Editor
Answer: B
Explanation:
In Databricks, to determine the owner of a managed table, you can utilize the Catalog Explorer feature. The steps are as follows:
Access Catalog Explorer:
In your Databricks workspace, click on the Catalog icon in the sidebar to open Catalog Explorer.
Navigate to the Table:
Within Catalog Explorer, browse through the catalog and schema to locate the specific managed table whose ownership you wish to verify.
View Table Details:
Click on the table name to open its details page.
Identify the Owner:
On the table's details page, review the Owner field, which displays the principal (user, service principal, or group) that owns the table.
This method provides a straightforward way to ascertain the ownership of managed tables within the Databricks environment. Understanding table ownership is essential for managing permissions and ensuring proper access control.
NEW QUESTION # 29
A data analyst is processing a complex aggregation on a table with zero null values and their query returns the following result: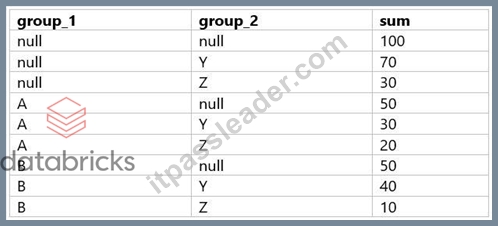
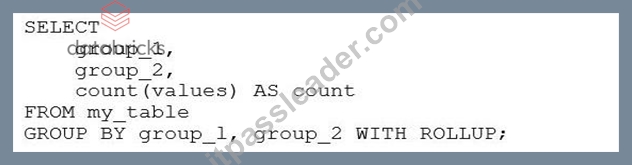
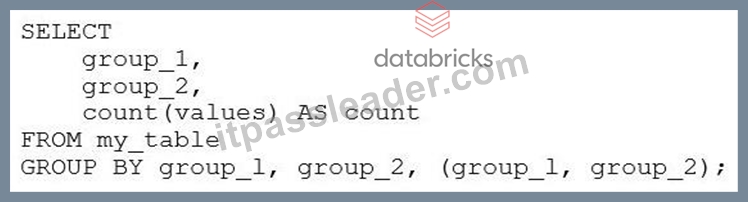
Which of the following queries did the analyst run to obtain the above result?
- A.
- B.
- C.
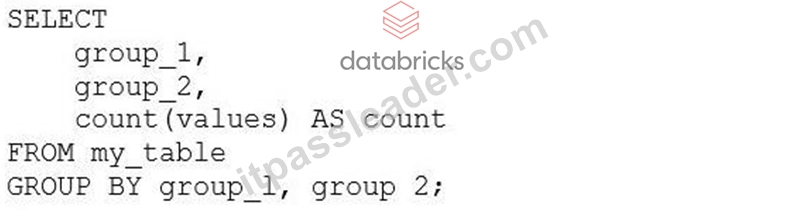
- D.
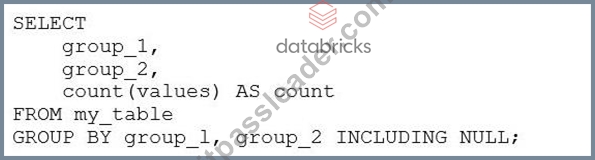
- E.
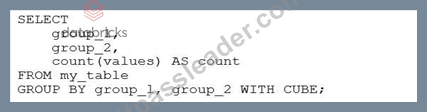
Answer: A
Explanation:
The result set provided shows a combination of grouping by two columns (group_1 and group_2) with subtotals for each level of grouping and a grand total. This pattern is typical of a GROUP BY ... WITH ROLLUP operation in SQL, which provides subtotal rows and a grand total row in the result set.
Considering the query options:
A) Option A: GROUP BY group_1, group_2 INCLUDING NULL - This is not a standard SQL clause and would not result in subtotals and a grand total.
B) Option B: GROUP BY group_1, group_2 WITH ROLLUP - This would create subtotals for each unique group_1, each combination of group_1 and group_2, and a grand total, which matches the result set provided.
C) Option C: GROUP BY group_1, group 2 - This is a simple GROUP BY and would not include subtotals or a grand total.
D) Option D: GROUP BY group_1, group_2, (group_1, group_2) - This syntax is not standard and would likely result in an error or be interpreted as a simple GROUP BY, not providing the subtotals and grand total.
E) Option E: GROUP BY group_1, group_2 WITH CUBE - The WITH CUBE operation produces subtotals for all combinations of the selected columns and a grand total, which is more than what is shown in the result set.
The correct answer is Option B, which uses WITH ROLLUP to generate the subtotals for each level of grouping as well as a grand total. This matches the result set where we have subtotals for each group_1, each combination of group_1 and group_2, and the grand total where both group_1 and group_2 are NULL.
NEW QUESTION # 30
In which of the following situations will the mean value and median value of variable be meaningfully different?
- A. When the variable contains no missing values
- B. When the variable contains no outliers
- C. When the variable is of the categorical type
- D. When the variable is of the boolean type
- E. When the variable contains a lot of extreme outliers
Answer: E
Explanation:
The mean value of a variable is the average of all the values in a data set, calculated by dividing the sum of the values by the number of values. The median value of a variable is the middle value of the ordered data set, or the average of the middle two values if the data set has an even number of values. The mean value is sensitive to outliers, which are values that are very different from the rest of the data. Outliers can skew the mean value and make it less representative of the central tendency of the data. The median value is more robust to outliers, as it only depends on the middle values of the data. Therefore, when the variable contains a lot of extreme outliers, the mean value and the median value will be meaningfully different, as the mean value will be pulled towards the outliers, while the median value will remain close to the majority of the data1. Reference: Difference Between Mean and Median in Statistics (With Example) - BYJU'S
NEW QUESTION # 31
......
Verified Databricks-Certified-Data-Analyst-Associate Dumps Q&As - 1 Year Free & Quickly Updates: https://troytec.itpassleader.com/Databricks/Databricks-Certified-Data-Analyst-Associate-dumps-pass-exam.html